CLS supports importing log files from AWS S3 buckets into log topics and performing search and analysis on the imported logs. You can complete data import by simply configuring it in the CLS console.
Prerequisites
You have activated CLS and created the corresponding resources, such as logsets and Log topics.
Prepare the log files to be imported in the AWS S3 bucket. You can go to the AWS console to view them.
You have obtained the AWS IAM user access key that can access the target bucket. The IAM user must have permissions to list and read target objects (s3:ListBucket and s3:GetObject).
1. Select Log Topic: You can select an existing log topic or create a new one to store data imported from AWS S3 to CLS.
2. Configure Data Source: Enter the AWS S3 region, bucket, access key, file path prefix, and compression mode, and preview the data to be imported.
3. Parsing Configuration: Configure the parsing format for imported files. Currently supported formats include single-line full text, multi-line full text, single-line regex, multi-line regex, JSON, and delimiter.
4. Index Configuration: Configure the index configuration for the current topic. Search requires index configuration to be enabled. If you select an existing log topic, the new index configuration takes effect only on data written after the modification.
Operation Steps
Step 1: Create/Select a Log Topic
Create a Log Topic
Using an Existing Log Topic
If you want to create a new log topic, perform the following operations:
2. In the left sidebar, click Log Topic, select the log topic to import, click the log topic name, and go to the log topic management page.
3. Select the Collection Configuration tab and click Create.
4. Select Data Import, locate and click AWS S3 Data Import, and enter the collection configuration process.
Step 2: Configure the Data Source
1. On the Data Source Configuration page, configure the following information in sequence:
Configuration Item
Required
Description
Task Name
Yes
Name of the import task. Supports letters, digits, underscores (_), and hyphens (-).
Job type
No
Select One-time import or Continuous import. One-time import is suitable for a single migration or verification; continuous import is suitable for continuously ingesting newly added matching objects.
Region
Yes
Region where the AWS S3 bucket resides. For example, ap-southeast-1.
Bucket name
Yes
Name of the S3 bucket that stores the logs to be imported. For example, example-log-bucket.
Access Key ID
Yes
Access key ID of the AWS IAM user.
Secret Access Key
Yes
Secret access key corresponding to the Access Key ID.
After logging in to the AWS console, click your username in the upper-right corner to go to Security credentials. In Access keys, click Create access key, and save the Access Key ID and Secret Access Key immediately after creation.
Custom Endpoint
No
If left blank, the standard AWS S3 endpoint is used. To use S3-compatible storage or a custom endpoint, enter it here.
File Path Prefix
No
Used to limit the import scope. You can enter a directory prefix, for example, logs/app/, or a complete object path, for example, logs/app/app.log. If left blank, all objects in the bucket are matched.
Compression Format
No
Select a mode that matches the actual compression format of the object. Supported formats include gzip, lzop, snappy, bzip2, zip, zstd, deflate, and lz4 (frame).
2. Click Preview. The system will select a path that matches the configuration rules for display and indicate the total number of files under the specified file prefix.
3. After confirming that the preview is correct, click Next.
Note:
If different formats cannot share the same parsing rule, split them into multiple import tasks by directory or complete object path.
Step 3: Parsing Configuration
On the parsing configuration page, configure the following information:
1. Extraction mode: The following extraction modes can be selected.
Single-Line Full-Text
Single-line - Full regex
Multi-line full-text
Multi-line - Full regex
JSON
Delimiter
A single-line full-text log refers to a log where each line represents a complete log entry. When collecting logs, CLS uses the line break \\n as the delimiter to mark the end of each log entry. For unified structured management, each log will have a default key-value pair __CONTENT__. However, the log data itself will not be processed in a structured manner, nor will log fields be extracted. The time attribute of a log is determined by the time when the log is collected.
Assume that the raw data of a log is:
Tue Jan 2212:08:15 CST 2019 Installed: libjpeg-turbo-static-1.2.90-6.el7.x86_64
The data collected into CLS is:
__CONTENT__:Tue Jan 2212:08:15 CST 2019 Installed: libjpeg-turbo-static-1.2.90-6.el7.x86_64
The single-line full regular expression format is usually used to process structured logs. This represents a log parsing mode in which multiple key-value pairs are extracted from a complete log entry using regular expressions.
http_user_agent: Mozilla/5.0 (Windows NT 10.0; WOW64; rv:64.0) Gecko/20100101 Firefox/64.0
remote_addr: 10.135.46.111
request_length: 782
request_method: GET
request_time: 0.354
request_url: /my/course/1
status: 200
time_local: [22/Jan/2019:19:19:30 +0800]
upstream_response_time: 0.354
Configure Single-line Full Regular Expression Mode:
1. On the Collection Configuration page, set "extraction mode" to Single-line Full regular expression, and enter a log example in the "log example" textbox.
2.
Define a regular expression according to the following rules:
The system provides two modes to define regular expressions: manual mode and auto mode. The system will extract key-value pairs for regular expression verification based on the mode you select and the defined regular expression.
Manual Mode
Automatic Mode
You can manually enter an expression to extract key-value pairs for verification:
(1) In the text box of Regular Expression, enter a regular expression.
(2) Click Verify and the system will judge whether the log sample matches the regular expression.
You can click Auto Regular Expression Tool to switch to auto mode:
(1) In the pop-up
Regular Expression Auto-Generation
modal view, based on your actual search and analysis needs, use the left mouse button to select the log content from which key-value pairs need to be extracted. Then, in the pop-up text box, enter the key name and click Confirm Extraction.
The system will automatically extract a regular expression for this part of the content, and the Automatically extraction results will appear in the key-value table on the right. The Extracted Regular Expression automatically generated based on the Automatically extraction results will appear in the table below.
(2) Repeat the above steps until all key-value pairs are extracted.
(3) Click OK. The system will automatically generate a complete regular expression based on the extracted key-value pairs.
Note:
Whether you use manual mode or automatic mode, after the definition is completed and verified, the extraction results will be displayed in the Log Extraction Results section. If the results do not meet your expectations, you can go back to edit the regular expression and verify it again.
You only need to define the key name for each key-value pair, and then you can use that name for log search and analysis.
More log verification:
1. When you have multiple complex log sample data entries, you can set Match More Logs to enable
to verify the pass rate of your regular expression samples.
2. Enter the log samples to be verified, separating multiple data entries with line breaks. Click Verify and the system will verify the pass rate of the samples. When
appears, the verification is passed.
Multi-line full-text logs refer to complete log entries that may span multiple lines (such as Java stack traces). In such cases, to enable the logging system to clearly distinguish between log entries, a first-line regular expression matching method is adopted. When a log line matches the predefined regular expression, it is identified as the start of a log entry, and the appearance of the next matching first line serves as the end marker for that log entry.
A multi-line full-text log will also have a default key-value pair __CONTENT__. However, the log data itself will not be processed in a structured manner, nor will log fields be extracted. The time attribute of a log is determined by the time when the log is collected.
__CONTENT__:2019-12-15 17:13:06,043 [main] ERROR com.test.logging.FooFactory:\\njava.lang.NullPointerException\\n at com.test.logging.FooFactory.createFoo(FooFactory.java:15)\\n at com.test.logging.FooFactoryTest.test(FooFactoryTest.java:11)
Configure Multi-line Full-Text Format:
1. On the Collection Configuration page, set Extraction Mode to Multi-line Full Text.
2. Define a regular expression based on the following rules. You can define the first-line regular expression in either of the following two ways: Auto-Generate or Enter Manually. The system will verify the regular expression based on the sample content.
Auto-Generate: Enter a log sample in the text box and click Auto-Generate. The system will automatically generate a first-line regular expression in the grayed-out text box.
Enter Manually: Enter a log sample in the text box, enter the first-line regular expression, and click Verify. The system will check whether the expression passes verification.
Configure Upload of Parsing Failure Logs:
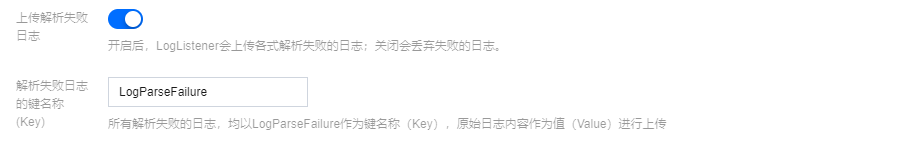
It is recommended to enable the upload of logs that failed to be parsed. After this feature is enabled, LogListener will upload various logs that failed to be parsed. If this feature is disabled, the logs that failed to be parsed will be discarded.
After this feature is enabled, you need to configure the key value for parsing failures (which is LogParseFailure by default). All logs that failed to be parsed are uploaded with the input content as the key name (Key) and the raw log content as the key value (Value).
After the system extracts the corresponding key-value pair based on the () capture group, you can customize the key name of each group as follows:
time: 2018-10-01T10:30:01,000`
level: INFO`
msg:java.lang.Exception: exception happened
at TestPrintStackTrace.f(TestPrintStackTrace.java:3)
at TestPrintStackTrace.g(TestPrintStackTrace.java:7)
at TestPrintStackTrace.main(TestPrintStackTrace.java:16)
Configure Multiline Full Regular Expression Mode
1. On the collection configuration page, set Extraction Mode to Multiline Full Regular Expression, and enter a log sample in the Log Sample text box.
2. Define the first-line regular expression based on the following rules: You can choose whether to enable Auto-Generate to define the first-line regular expression (if this feature is disabled, you can enter it manually) to determine the boundaries of multiline logs. After the expression is verified, the system will determine the number of logs that match the first-line regular expression.
Auto generate: Turn on Auto-Generate, and the system automatically generates the first-line regular expression in the grayed-out text box.
Manual input: In the text box, manually enter the first-line regular expression and click Verify. The system will determine whether the expression passes verification.
Extract Regular Expression
The system provides two modes to define regular expressions: manual mode and auto mode. You can either manually enter the expression to extract key-value pairs for verification, or click Auto-Generate Regular Expression to switch to automatic mode. The system will extract key-value pairs based on the selected mode and the defined regular expression for verification.
Manual Mode
Automatic Mode
(1) Enter a regular expression in the Extract Regular Expression text box.
(2) Click Verify and the system will judge whether the log sample matches the regular expression.
(1) In the pop-up
Regular Expression Auto-Generation
modal view, based on your actual search and analysis needs, select the log content from which key-value pairs need to be extracted. Then, in the pop-up text box, enter the key name and click Confirm Extraction.
(2) The system will automatically extract a regular expression for this part of the content, and the automatic extraction results will appear in the key-value table.
(3) Repeat the above steps until all key-value pairs are extracted.
(4) Click OK. The system will automatically generate a complete regular expression based on the extracted key-value pairs.
Note:
Whether you choose automatic mode or manual mode, after the regular expression extraction mode is defined and verified, the extraction results will be displayed in the Extraction Results section. You only need to define the key name for each key-value pair, which can then be used for log search and analysis.
Match More Logs:
1. When your log data is complex, you can enable Match More Logs to verify the pass rate of your regular expression samples.
2. Enter multiple log samples to be verified and click Verify. The system will verify the pass rate of the samples. When
appears, the verification is passed.
Configure Log Timestamp Source:
You can choose either log collection time or specified log field as the log timestamp:
Log Collection Time
Specifying Log Fields
Use the log collection time as the log time.
Use the value of the specified field in the log as the log time.
Select the extracted Value from the Log Time Gield as the log time.
In Time Parsing Format, manually enter or select the corresponding parsing expression. For example: the value representing time in logs is 07/Jul/2025:19:19:30 +0800, and the parsing format is %d/%b/%Y:%H:%M:%S %z. For more information, please refer to configure time format.
Click Verify.
Note:
If the time format is entered incorrectly, the log time will be based on the collection time.
Configure Upload of Parsing Failure Logs:
It is recommended to enable the upload of logs that failed to be parsed. After this feature is enabled, LogListener will upload various logs that failed to be parsed. If this feature is disabled, the logs that failed to be parsed will be discarded.
After this feature is enabled, you need to configure the key value for parsing failures (which is LogParseFailure by default). All logs that failed to be parsed are uploaded with the input content as the key name (Key) and the raw log content as the key value (Value).
agent: Mozilla/5.0 (Windows NT 10.0; WOW64; rv:64.0) Gecko/20100101 Firefox/64.0
body_sent: 23
http_host: 127.0.0.1
method: POST
referer: http://127.0.0.1/my/course/4
remote_ip: 10.135.46.111
request: POST /event/dispatch HTTP/1.1
response_code: 200
responsetime: 0.232
time_local: 22/Jan/2019:19:19:34 +0800
upstreamhost: unix:/tmp/php-cgi.sock
upstreamtime: 0.232
url: /event/dispatch
xff: -
Configure Log Timestamp Source:
Log Collection Time
Specifying Log Fields
Use the log collection time as the log time.
Use the value of the specified field in the log as the log time.
In the Log Time Field, manually enter the time field specified in the JSON as the log time.
In Time Parsing Format, manually enter or select the corresponding parsing expression. For example: the value representing time in logs is 07/Jul/2025:19:19:30 +0800, and the parsing format is %d/%b/%Y:%H:%M:%S %z. For more information, please refer to configure time format.
Click Verify.
Note:
If the time format is entered incorrectly, the log time will be based on the collection time.
Configure Upload of Parsing Failure Logs:
It is recommended to enable the upload of logs that failed to be parsed. After this feature is enabled, LogListener will upload various logs that failed to be parsed. If this feature is disabled, the logs that failed to be parsed will be discarded.
After this feature is enabled, you need to configure the key value for parsing failures (which is LogParseFailure by default). All logs that failed to be parsed are uploaded with the input content as the key name (Key) and the raw log content as the key value (Value).
When the delimiter for log parsing is specified as :::, this log will be divided into eight fields, and each of these fields will be assigned a unique key, as shown below:
IP: 10.20.20.10 -
bytes: 35
host: 127.0.0.1
length: 647
referer: http://127.0.0.1/
request: GET /online/sample HTTP/1.1
status: 200
time: [Tue Jan 22 14:49:45 CST 2019 +0800]
Configure Delimiter Mode:
1. Set Extraction Mode to Delimiter.
2. Select Delimiter and enter a log sample in the Log Sample text box, and then click Extract.
The system splits the log sample according to the determined delimiter and displays it in the extraction result panel. Define a unique key for each field. Currently, log collection supports multiple delimiters; common delimiters include: space, tab, comma, semicolon, and vertical bar. If the delimiter used in your log data is another symbol, such as :::, you can also parse it through a custom delimiter.
Configure Log Timestamp Source:
Log Collection Time
Specifying Log Fields
Use the log collection time as the log time.
Use the value of the specified field in the log as the log time.
Select the extracted Value from the Log Time Gield as the log time.
In Time Parsing Format, manually enter or select the corresponding parsing expression. For example: the value representing time in logs is 07/Jul/2025:19:19:30 +0800, and the parsing format is %d/%b/%Y:%H:%M:%S %z. For more information, please refer to configure time format.
Click Verify.
Note:
If the time format is entered incorrectly, the log time will be based on the collection time.
Configure Upload of Parsing Failure Logs:
It is recommended to enable the upload of logs that failed to be parsed. After this feature is enabled, LogListener will upload various logs that failed to be parsed. If this feature is disabled, the logs that failed to be parsed will be discarded.
After this feature is enabled, you need to configure the key value for parsing failures (which is LogParseFailure by default). All logs that failed to be parsed are uploaded with the input content as the key name (Key) and the raw log content as the key value (Value).
2. Filter:
Filters help you add log collection filtering rules according to business requirements, to screen out valuable log data. Filtering rules are Perl regular expressions. The created rules are inclusion rules, meaning only logs matching the regular expression will be collected and reported.
For delimiter-formatted logs, filtering rules need to be configured based on custom key-value pairs. For example, after a sample log is parsed in delimiter mode, if you want all log data with the status field equal to 400 or 500 to be collected, set key as status, and set the filter rule as 400|500.
3. Metadata: includes two types: bucket (bucket name) and object (full object path). Selected metadata will be imported together with logs in the format of __TAG__.{metadata}:xxx. For example: __TAG__.object: csv/object.gz.
4. If you need to further process the collected CLS logs, such as structuring, masking, or filtering, before writing them into the log topic, you can click Data Processing at the bottom of the page, add data processing, and then configure the index.
For data processing-related operations, see the Preprocessing of Data tab in Creating Processing Task.
Data processing will incur fees. For details, see Billing Overview.
5. Click Next.
Step 4: Performing Index Configuration
1. On the Index Configuration webpage. For configuration details, please see index configuration.
Note:
Index configuration must be enabled before you can perform searches.
2. Click Submit to go to the index configuration confirmation page. Click OK.
If you want the index configuration to take effect only on newly written logs, click OK. If you want the configuration to take effect on historical data, click OK, and then see Rebuild Index for further settings.
3. The operation is successful. The collection configuration step ends.